

Databricks pipeline
Trace how data flows through the tables and views of a Databricks declarative pipeline.
Diagram · origin tag databricks/pipeline · Data platforms & pipeline orchestration
Availability
| Host | State | How to get it |
|---|---|---|
| Standalone | Prototype | Not yet released |
| Desktop | Prototype | Not yet released |
| IntelliJ Platform | Not planned | Not planned |
| Visual Studio Code | Not planned | Not planned |
| Eclipse | Not planned | Not planned |
| ThinkRail | Not planned | Not planned |
| Notion | Not planned | Not planned |
| Claude | Not planned | Not planned |
What it is for
Databricks declarative pipeline (the datasets, streaming tables and materialized views it declares, and the flows between them)
Why a specialized view helps
Declared datasets only reveal their lineage when drawn as a graph; a specialized view follows each flow from source to materialized view.
File formats
Not described yet.
Screenshots
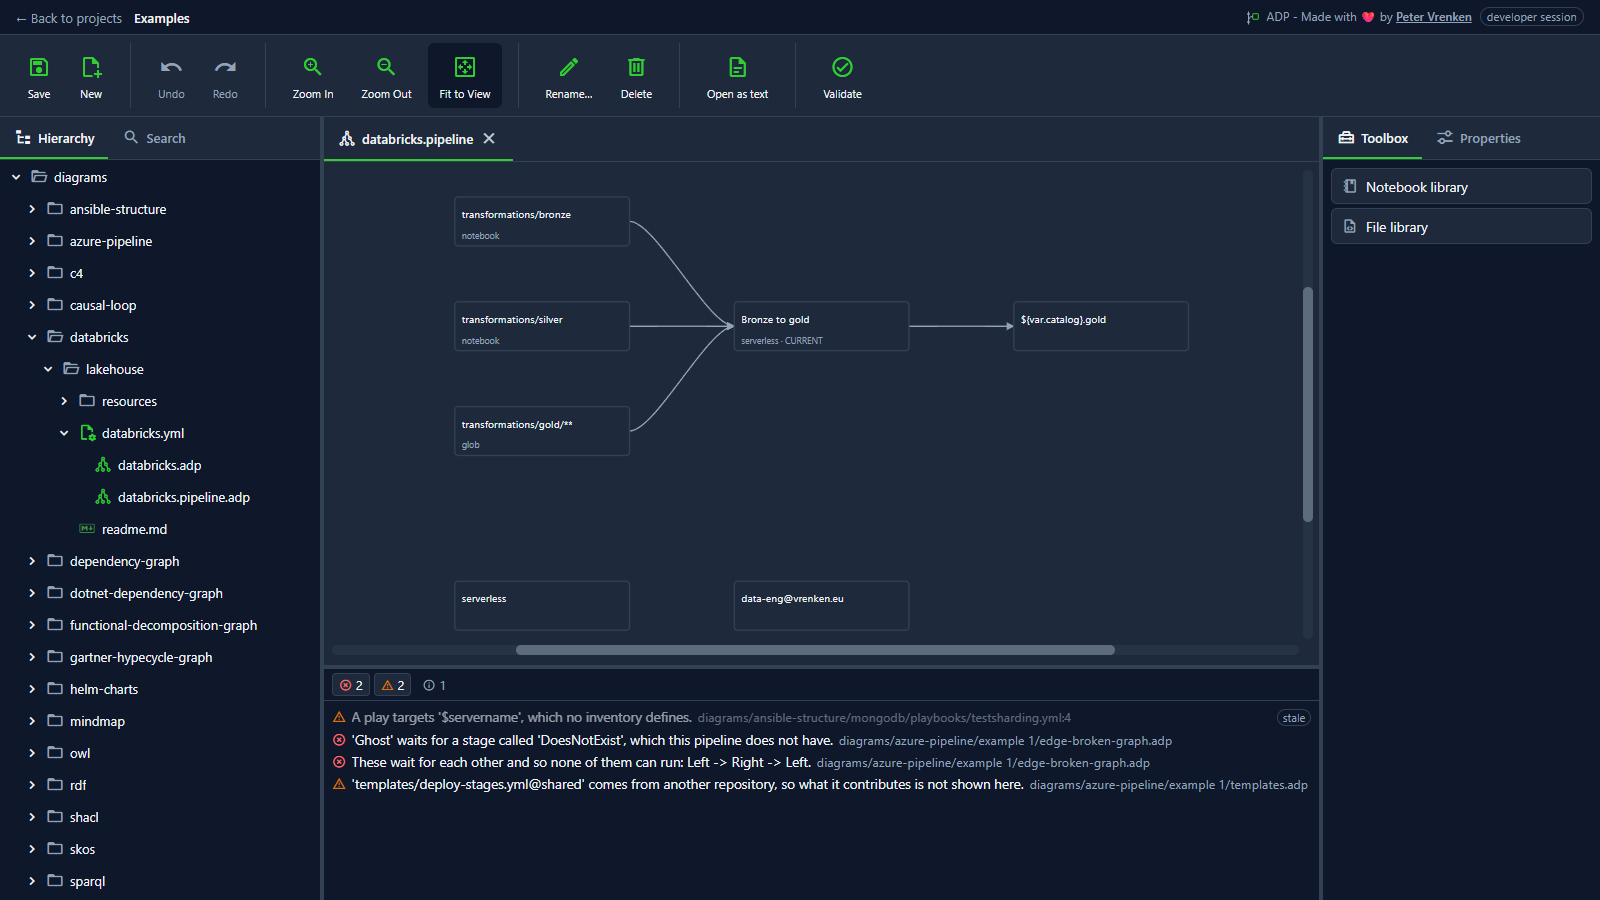
Standalone, at 3e2df46
What is visible: Three source libraries flowing into the Bronze to gold pipeline and on to its target catalog, with the compute and notification cards below. Nothing selected.
Why it matters: Source libraries flow into the pipeline and on to its target catalog, with compute and notifications alongside, so the data's path through the declarative pipeline is traceable from start to end.
Licence: Apache-2.0
Background
Focus areas
Sources
etalii-adp/etalii.adp.ide.standalone@9b232f0docs/tools.md, licence Apache-2.0etalii-adp/etalii.adp.ide.intellij@dc9c697docs/tools.md, licence Apache-2.0etalii-adp/etalii.adp.ide.vscode@ab93d8fdocs/tools.md, licence Apache-2.0etalii-adp/etalii.adp.ide.standalone@3e2df46docs/screenshots/databricks-pipeline.png, licence Apache-2.0- Notion, edited (page
3e7be2fd-05b6-81ec-bce3-e238bf434d90), licence Apache-2.0
